Official · E2 · artifact verified
Check LLM citations against source context
An official cookbook combines exact quote matching with a Jev relation judgment to label citations verified, unsupported, contradicted, or fabricated.
01 · Role in the system
What Jev does here
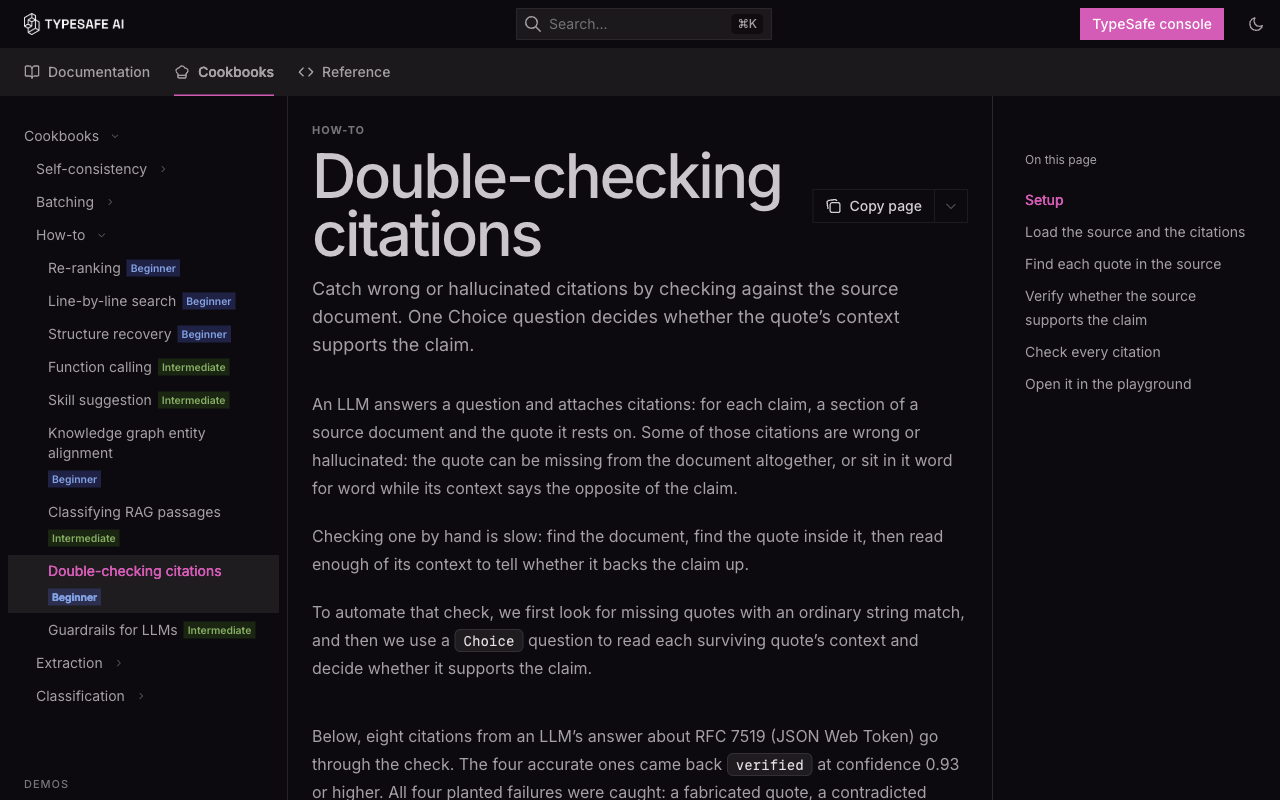
For each quote that exists in the source, Jev receives the claim and surrounding RFC section and chooses whether the section supports the claim, contradicts it, or says nothing about it. Code normalizes and locates quotes first, marks missing quotes as fabricated without a model call, maps the relation to a verdict, and routes low-confidence answers to human review.
Code first, model only when it matters
The pipeline checks quotes against the source with exact matching before any model call, and a quote that simply is not there is labeled fabricated without spending a judgment. Only quotes that do appear in the source reach Jev, which answers one bounded question: does this RFC section support the claim, contradict it, or stay silent about it?
The routing logic after the judgment is as instructive as the judgment. Missing quotes are fabrication, supported quotes pass, and low-confidence answers go to human review by threshold — a policy decision living in code where it can be tightened without touching the model.
A fixture built to fail, and why that matters
The published fixture contains eight citations, four of them deliberately edited to fail. That makes it a mechanism demonstration, not an accuracy benchmark — the record says so explicitly, because a four-of-eight failure rate on purpose-built failures would be meaningless as a statistic.
The honest weakness is exactness: a shortened or lightly paraphrased quote reads as fabricated even when the substance is present, and confidence thresholds need calibration on the target corpus before the human-review rate means anything. Both limits travel with the record.
02 · Control boundary
Where Jev sits
Deterministic source matching gates one bounded relation Choice; confidence thresholds decide whether code accepts or reviews the verdict.
Code owns the loop, permissions, thresholds, validation, and side effects. Jev owns only the bounded judgments described above.
03 · Known limits
What this evidence does not prove
- The published fixture contains eight citations, including four deliberately edited failures, so it is not a representative accuracy benchmark.
- Exact matching can label a shortened or lightly paraphrased quote as fabricated, and confidence thresholds require calibration on the target corpus.
04 · Attribution
Public sources
This is an Official record: the example was published by TypeSafe itself.
- TypeSafe ↗Official · cookbook · public · checked 2026-09-18