Community · E2 · artifact verified
Assess a simulated company under attack
A local cybersecurity lab replays synthetic telemetry and asks Jev for compromise probability, classification, severity, and an advisory response as evidence accumulates.
01 · Role in the system
What Jev does here
For each investigated identity the lab sends a bounded evidence window and asks Jev four questions: a Noul compromise probability, a Choice classification with its distribution, a weighted 0-3 severity Score, and a Choice advisory response. Scenario ground truth stays separate from the model's input, and code owns telemetry generation, windowing, decision policies, and the investigation workspace. A packaged demo replays recorded jev-1.13.0 responses offline, and saved checkpoints expose exact inputs, distributions, and timing.
Four judgments per identity, ground truth walled off
For each investigated identity the lab asks Jev four typed questions at once: a compromise probability, a classification with its full distribution, a weighted zero-to-three severity score, and an advisory response. Scenario ground truth never enters the model's input, and code owns telemetry generation, windowing, and the investigation workspace.
The replayable checkpoints are what make this auditable. Saved states expose the exact inputs, distributions, and timing behind every advisory, and a packaged demo replays recorded jev-1.13.0 responses offline — the judgment trail can be re-examined without re-running anything.
Advisory by design, synthetic by necessity
The telemetry is synthetic and the lab never touches real infrastructure, so every judgment is advisory — the record is about the assessment pipeline's shape, not about detection performance. The published acceptance records cover fixed fixtures and browser performance, not accuracy against a labeled benchmark.
Within those limits, the record demonstrates something security tooling needs: evidence windows that bound what the model sees, typed outputs a policy engine can consume, and an audit trail for every judgment. The missing number — detection accuracy on labeled data — is the same one missing across the security cluster.
02 · Control boundary
Where Jev sits
Sliding telemetry windows to parallel typed judgments; deterministic policy turns judgments into an advisory investigation trail with replayable checkpoints.
Code owns the loop, permissions, thresholds, validation, and side effects. Jev owns only the bounded judgments described above.
03 · Known limits
What this evidence does not prove
- Telemetry is synthetic and the lab never touches real infrastructure, so every judgment is advisory only.
- The published acceptance records cover fixed fixtures and browser performance, not detection accuracy against a labeled benchmark.
04 · Attribution
Public sources
This is a Community record: the project was published by a third-party community author.
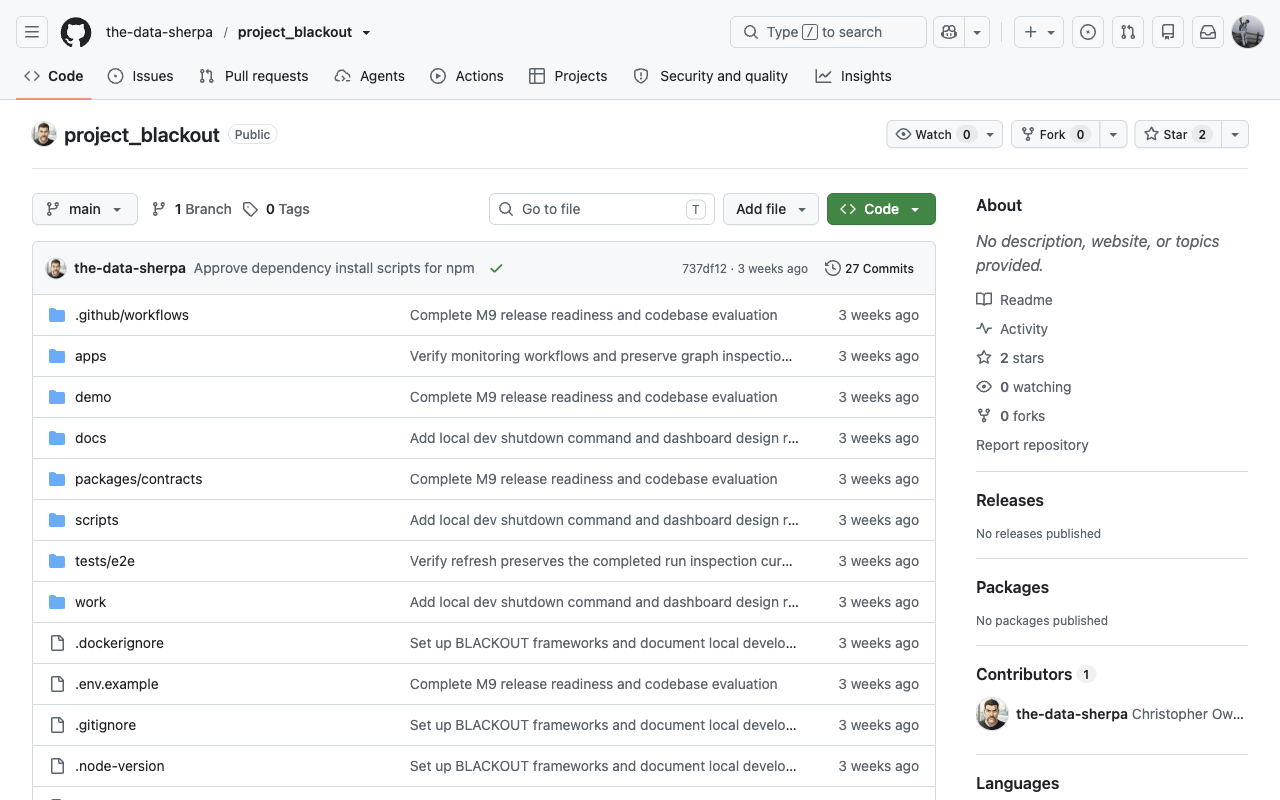
- the-data-sherpa ↗Community · github · public · checked 2026-09-18